MUSE Lab

MUSE Lab

Multimodal Understanding and Synthesis for Explainability

We build trustworthy generative AI构建可信的生成式 AI

News最新
01

About the Lab实验室简介

MUSE Lab stands for Multimodal Understanding and Synthesis for Explainability. The Muses were the Greek goddesses of art and inspiration: we want generative AI to be just as creative, and at the same time controllable, interpretable and trustworthy.

MUSE Lab 的全称是 Multimodal Understanding and Synthesis for Explainability,即“面向可解释性的多模态理解与生成”。MUSE 也是希腊神话中司掌艺术与灵感的缪斯女神:我们希望生成式 AI 像缪斯一样富有创造力,同时可控、可解释、值得信任。

Yifan Yuan 袁一帆

Principal Investigator实验室负责人

Yifan Yuan 袁一帆袁一帆 Yifan Yuan

Assistant Professor, College of AI, Shenzhen University深圳大学人工智能学院 助理教授 · 硕士生导师

  1. Multimodal · 多模态

    Images, video and language, modelled together.

    联合建模图像、视频与语言。

  2. Understanding · 理解

    Knowing what a model sees, and why it fails.

    看懂模型理解了什么、为什么会出错。

  3. Synthesis · 生成

    Generating and editing content with precise control.

    精确、可控地生成与编辑内容。

  4. Explainability · 可解释

    Opening the black box, so that people can trust it.

    打开黑箱,让人能够信任。

02

Research Directions研究方向

Image & Video Generation and Editing图像视频生成与编辑

Why diffusion models fail on certain concepts, and how to generate and edit images and videos precisely while keeping meaning and identity intact.

探究扩散模型为何在特定概念上失效,在保持语义与身份不变的前提下,精确地生成与编辑图像和视频。

  • Inside diffusion models扩散模型的内部机理
  • Disentangled, controllable editing属性解耦与可控编辑
  • Identity-preserving image and video editing保持身份的图像与视频编辑
  • Reliability of generative editing生成式编辑的可靠性评估

Representative work代表工作

Multimodal Understanding & Applications多模态理解与应用

Models that understand video, images and text, put to work on real tasks.

让模型读懂视频、图像与文字,并落到真实场景中。

  • Moment retrieval and highlights视频时刻检索与高光检测
  • Story-aware video editing懂剧情的智能剪辑
  • Virtual try-on quality checks虚拟试衣失真检测
  • Multimodal retrieval and moderation多模态信息检索与审核

Trustworthy LLMs & Agents可信大模型与智能体

LLMs and agents that stay reliable through long dialogues and multi-agent workflows: they keep to their constraints, catch their own mistakes and can show their sources.

让大模型与智能体在长程对话与多智能体协作中保持可靠:守得住约束、查得出错误、说得出依据。

  • Predicting and steering hallucinations幻觉风险的预测与干预
  • State integrity in long dialogues长程对话的状态保持
  • Constraints across agent handoffs多智能体交接中的约束保持
  • Reflective search for code generation代码生成的反思式搜索
  • Grounded survey writing有依据的综述写作

Representative work代表工作

Emotion AI情感智能

AI that reads human emotion faithfully and offers the right kind of companionship and support.

让 AI 读懂人的情绪,给出恰当的陪伴与支持。

  • Multimodal emotion recognition多模态情绪识别
  • Hallucinations in emotion descriptions情绪描述中的幻觉
  • Emotional support conversation情感支持对话
  • Companions with memory and personality有记忆、有人格的 AI 伙伴

Representative work代表工作

Embodied AI具身智能

Robots that perceive, plan and act reliably through long tasks, and keep improving after deployment.

让机器人在长周期任务中看得懂、想得清、做得稳。

  • End-to-end long-horizon decisions端到端长程决策
  • Test-time adaptation for VLA modelsVLA 模型的测试时自适应
  • Fine manipulation for industry工业场景中的精细操作
03

Featured Work代表作

Concept Brittleness

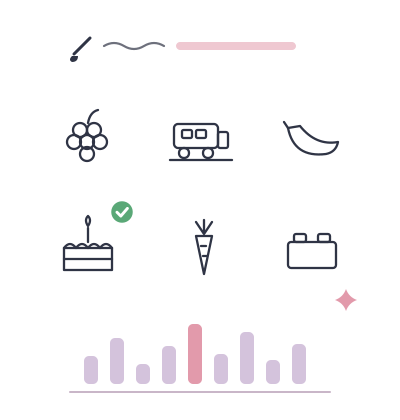
Asked for an ink painting, why does an image generator paint grapes in black-and-white ink but always paint a cake in color? We found what makes the result depend on the object being drawn, and fix this “object-level concept brittleness” without any training.

同样画一幅水墨画,为什么图像生成模型能把葡萄画成黑白水墨色,而却把蛋糕始终画成彩色的?我们找到了这种因为画的物体不同而产生差异的原因,无需训练即可修正这种“物体级的概念脆弱性”。

Learn more了解更多Code

Semantic Discrepancy

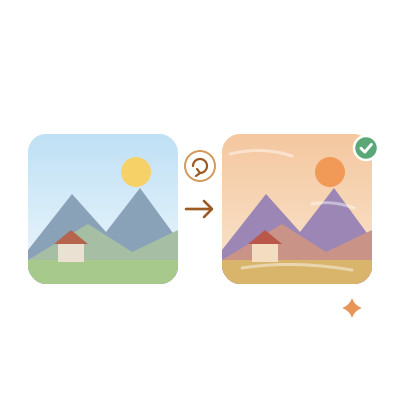
Turning a photo into a painting, diffusion models invent things that were never there. One inversion step fixes it.

照片转油画时,模型会凭空“脑补”原图里没有的东西。一步反演就能修正。

Learn more了解更多Code

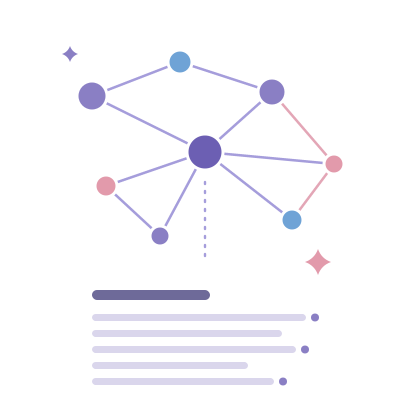
SurveyGraph

An AI that first maps how a research field evolved, then writes a fully cited survey along that map.

让 AI 先画出一个领域的“方法—实体”知识图谱,再沿着它写出一篇有据可查的学术综述。

Learn more了解更多Code

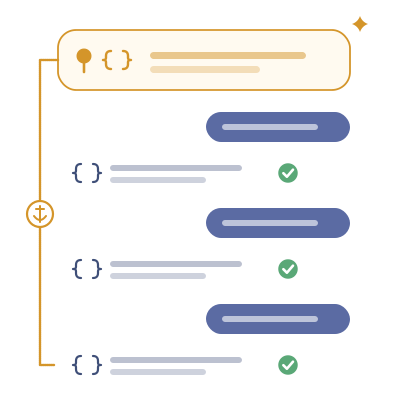
StateTrack

LLMs still remember the rules you set; deep into a conversation they quietly stop following them. We found this collapse and measured it.

大模型还记得你定下的规则,却在长对话里悄悄不再遵守。我们发现并量化了这种“状态崩塌”。

Learn more了解更多Code

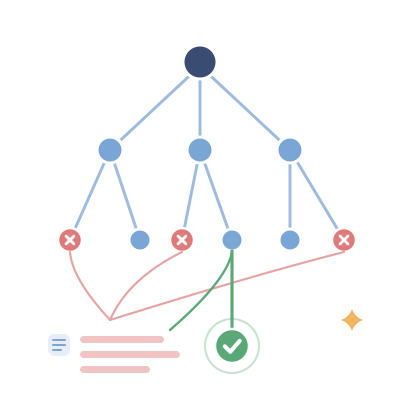
ReMCTS

Code-writing agents try many programs in a search tree, and every failed branch teaches the others.

写代码的智能体在一棵搜索树上多路尝试,失败分支的经验会分享给其他分支,少走弯路。

Learn more了解更多Code

04

Latest News最新动态

05

Publications论文成果

2026

  1. ACM MM 2026
    Interpreting Object-Dependent Concept Brittleness in Text-to-Image Diffusion Models Yifan Yuan*, Xiangyu Liu*, Hongming Shan, Yu Han, Yu Jiang, Hao Tan, Junping Zhang, Linlin Shen†. CCF A[Paper][Code]
  2. EMNLP 2026
    When LLMs Forget What They Believe: Characterizing State Integrity Collapse in Long-Horizon Dialogues Yancheng Zhu, Yifan Yuan†. [Paper][Code]
  3. EMNLP 2026
    ReMCTS: Reflection-Enhanced Monte Carlo Tree Search for Code Generation Wang Huifei, Huang Xinying, Sun Yiheng, Yifan Yuan†. [Paper][Code]
  4. EMNLP 2026
    SurveyGraph: Generating Academic Surveys via Methods-Entity Knowledge Graphs Yifan Yuan, Yancheng Zhu, Zuoyu Zhang, Xiaogang Peng†. [Paper][Code]
  5. Preprint 2026
    When “Must” Becomes “Maybe”: Erosion of Workflow Constraints in LLM Agent Handoffs Yiheng Sun, Huifei Wang, Yancheng Zhu, Zhenyu Li, Zebin Zhao, Yifan Yuan. arXiv:2608.24569. [Paper]

2025

  1. IEEE/CAA JAS 2025
    Dissecting and Mitigating Semantic Discrepancy in Stable Diffusion for Image-to-Image Translation Yifan Yuan, Guanqun Yang, James Z. Wang, Hui Zhang, Hongming Shan, Feiyue Wang†, Junping Zhang. IEEE/CAA Journal of Automatica Sinica, 2025, 12(4): 705–718. JCR Q1 · IF 19.3[Paper][Code]

2023

  1. ICASSP 2023
    DO-FAM: Disentangled Non-Linear Latent Navigation for Facial Attribute Manipulation Yifan Yuan*, Siteng Ma*, Hongming Shan, Junping Zhang. IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2023. [Paper]
  2. Book Chapter 2023
    High-Speed Joint Learning of Action Units and Facial Expressions Feng Xu, Yifan Yuan, Junping Zhang, James Z. Wang. Chapter 7 in Modeling Visual Aesthetics, Emotion, and Artistic Style, Springer, 2023. [Paper]
  3. Book Chapter 2023
    ExpressionFlow: A Microexpression Descriptor for Efficient Recognition Feng Xu, Yifan Yuan, Junping Zhang, James Z. Wang. Chapter 8 in Modeling Visual Aesthetics, Emotion, and Artistic Style, Springer, 2023. [Paper]

2022

  1. ICASSP 2022
    VR-FAM: Variance-Reduced Encoder with Nonlinear Transformation for Facial Attribute Manipulation Yifan Yuan, Siteng Ma, Junping Zhang. IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP), 2022: 1755–1759. [Paper]

2020

  1. JIG 2020
    Spatiotemporal Attention Network for Microexpression Recognition Guohao Li, Yifan Yuan, Xianye Ben, Junping Zhang. Journal of Image and Graphics (中国图象图形学报), 2020, 25(11): 2380–2390. [Paper]
06

Projects科研项目

PI主持2025.08 – 2028.08

Reliability Evaluation and Controllable Editing Mechanisms for Generative Image Editing生成式图像编辑的可靠性评估与可控编辑机制研究

Measures whether AI image edits are correct and reliable, and makes editing change only what you ask for while keeping the rest intact.

评估 AI 修图改得对不对、稳不稳,并让编辑只改想改的地方,其余内容保持不变。

Shenzhen University Research Start-up Fund for Young Faculty深圳大学青年教师科研启动经费

Main Participant主要参与人2025.10 – 2028.09

Embodied-Intelligence Foundation Models for Industrial Humanoid Robots人形机器人工业具身智能基座大模型与垂直领域示范应用

Develops an embodied foundation model for industrial humanoid robots, so they can perceive the workplace, plan their actions and carry out production tasks, demonstrated in specific industries.

为工业人形机器人研发具身智能基座大模型,让机器人看懂现场、规划动作、完成生产任务,并在具体行业中示范应用。

Shenzhen Key Industry R&D Program深圳市重点产业研发计划

Lead Researcher主要负责人2025.06 – 2026.12

Intelligent Models for Multimodal Information Retrieval, Review and Moderation多模态信息检索、审查与管控智能模型研究

Develops models that understand images, video and text together, to find what is needed in large volumes of content and flag what needs review and moderation.

研发同时读懂图像、视频和文字的模型,从海量信息中检索所需内容,并识别需要审查和管控的信息。

Industry project with China Mobile横向项目,中国移动

Participant参与2026.01 – 2028.12

AI Virtual Patients for Clinical Teaching in Gastroenterology面向消化科临床教学的AI虚拟病人技术研究与应用

Builds AI virtual patients that act out real consultations, so gastroenterology students can practise history-taking and diagnosis as often as they need.

打造能模拟真实问诊的 AI 虚拟病人,让消化科医学生反复练习问诊和诊断。

Guangdong Natural Science Foundation, General Program广东省自然科学基金面上项目

Participant参与2022.01 – 2025.12

Deep Learning Based on Graph Convolutional Networks and Disentangled Learning基于图卷积神经网络和解耦学习的深度学习研究

Studies graph convolutional networks and disentangled representation learning, so models learn clearer, more interpretable features from complex relational data.

研究图卷积网络与解耦表示学习,让模型从复杂的关联数据中学到更清晰、更可解释的特征。

National Natural Science Foundation of China, General Program国家自然科学基金面上项目

Participant参与2019.06 – 2022.05

Key Theories and Technologies of Human–Robot Collaboration Based on Imitation Learning from Demonstration基于示教模仿学习的人机协同关键理论与技术

Teaches robots manipulation skills from human demonstrations, for safe and efficient human–robot collaboration.

让机器人看人示范就能学会操作技能,实现安全、高效的人机协作。

National Key R&D Program of China, No. 2018YFB1305104国家重点研发计划(十三五),项目编号 2018YFB1305104
07

Contact联系我们

Research and business collaborations are welcome. Get in touch:欢迎科研与商业合作,有合作意向欢迎联系我们: