EMNLP 2026
StateTrack
When LLMs Forget What They Believe: Characterizing State Integrity Collapse in Long-Horizon Dialogues
LLMs still remember the rules you set; deep into a conversation they quietly stop following them. We found this collapse and measured it.
大模型还记得你定下的规则,却在长对话里悄悄不再遵守。我们发现并量化了这种“状态崩塌”。
Overview概览
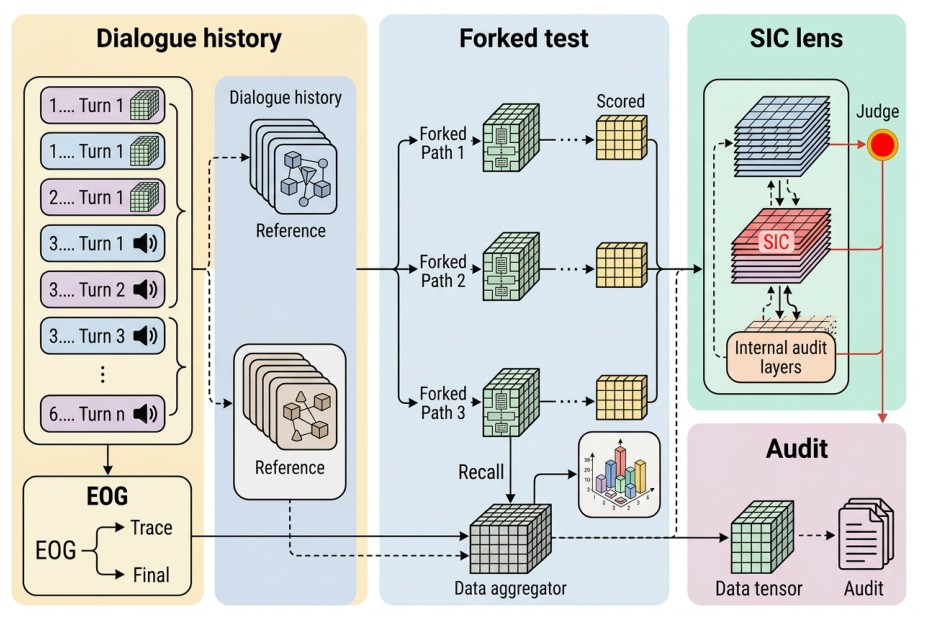
Assistants must keep obeying user-set constraints — formats, personas, safety boundaries — over many turns, but evaluations mostly test instruction following in a single turn or a short exchange. We identify a subtle but dangerous failure, State Integrity Collapse: asked about it, the model can still restate the constraint, yet its next answers stop following it — unlike ordinary forgetting, this is not fixed by longer context or memory retrieval. We build StateTrack-Bench, which plants one persistent constraint (numerical, format, persona, factual-memory or logical) in a conversation, checks compliance at increasing dialogue depths, and uses a forked recall audit to tell forgetting apart from remembering without complying. Across seven models, 88.6% of failures are such behavioral drift rather than forgetting, and our Structured State Anchoring recovers up to 24.4 points.
对话助手需要在很多轮对话里一直遵守用户设定的约束(格式、角色、安全边界等),但现有评测大多只看单轮或短对话里能否遵守指令。我们发现一种隐蔽而危险的失败:问起来模型还能复述约束,接下来的回答却不再执行——我们称之为“状态完整性崩塌”,它不同于普通的遗忘,单靠更长的上下文或记忆检索解决不了。我们构建了 StateTrack-Bench:在对话中设定一条持续约束(数值、格式、角色、事实记忆、逻辑规则五类),在不同对话深度检验模型是否仍然遵守,并用“分叉回忆审计”区分“记不住”和“记得但不做”。在七个主流模型上,88.6% 的失败属于“记得但不做”的行为漂移而非遗忘;我们提出的结构化状态锚定最多可挽回 24.4 个百分点。
Highlights要点
- 88.6% of failures are behavioral drift (remembering the rule but not following it) rather than forgetting.88.6% 的失败是“记得但不做”的行为漂移,而不是遗忘。
- StateTrack-Bench plants five kinds of persistent constraints and checks them at increasing dialogue depths, with a forked recall audit.StateTrack-Bench:五类持续约束,在不同对话深度检验,并用分叉回忆审计区分“记不住”和“不去做”。
- Structured State Anchoring recovers up to 24.4 points.结构化状态锚定最多可挽回 24.4 个百分点。
Method方法
Citation引用
@inproceedings{zhu2026statetrack,
  title     = {When LLMs Forget What They Believe: Characterizing State Integrity Collapse in Long-Horizon Dialogues},
  author    = {Yancheng Zhu and Yifan Yuan},
  booktitle = {Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing},
  year      = {2026},
  url       = {https://arxiv.org/abs/2610.31314}
}More featured work更多代表作
 Concept BrittlenessAsked for an ink painting, why does an image generator paint grapes in black-and-white ink but always paint a cake in color? We found what makes the result depend on the object being drawn, and fix this “object-level concept brittleness” without any training.同样画一幅水墨画,为什么图像生成模型能把葡萄画成黑白水墨色,而却把蛋糕始终画成彩色的?我们找到了这种因为画的物体不同而产生差异的原因,无需训练即可修正这种“物体级的概念脆弱性”。
 Semantic DiscrepancyTurning a photo into a painting, diffusion models invent things that were never there. One inversion step fixes it.照片转油画时,模型会凭空“脑补”原图里没有的东西。一步反演就能修正。
 SurveyGraphAn AI that first maps how a research field evolved, then writes a fully cited survey along that map.让 AI 先画出一个领域的“方法—实体”知识图谱,再沿着它写出一篇有据可查的学术综述。
 ReMCTSCode-writing agents try many programs in a search tree, and every failed branch teaches the others.写代码的智能体在一棵搜索树上多路尝试,失败分支的经验会分享给其他分支,少走弯路。